Measure first, ship second: the measurement layer is where AI work stalls or pays
Six developer stories converge on one finding: scheduling, benchmarks, and audit trails — not bigger models — decide whether AI work ships or stalls.
30 unguided agents ran the same dataset and produced 18 incompatible pipelines.
That is this edition's developer story in one line: the model is rarely the bottleneck anymore. The measurement layer is.
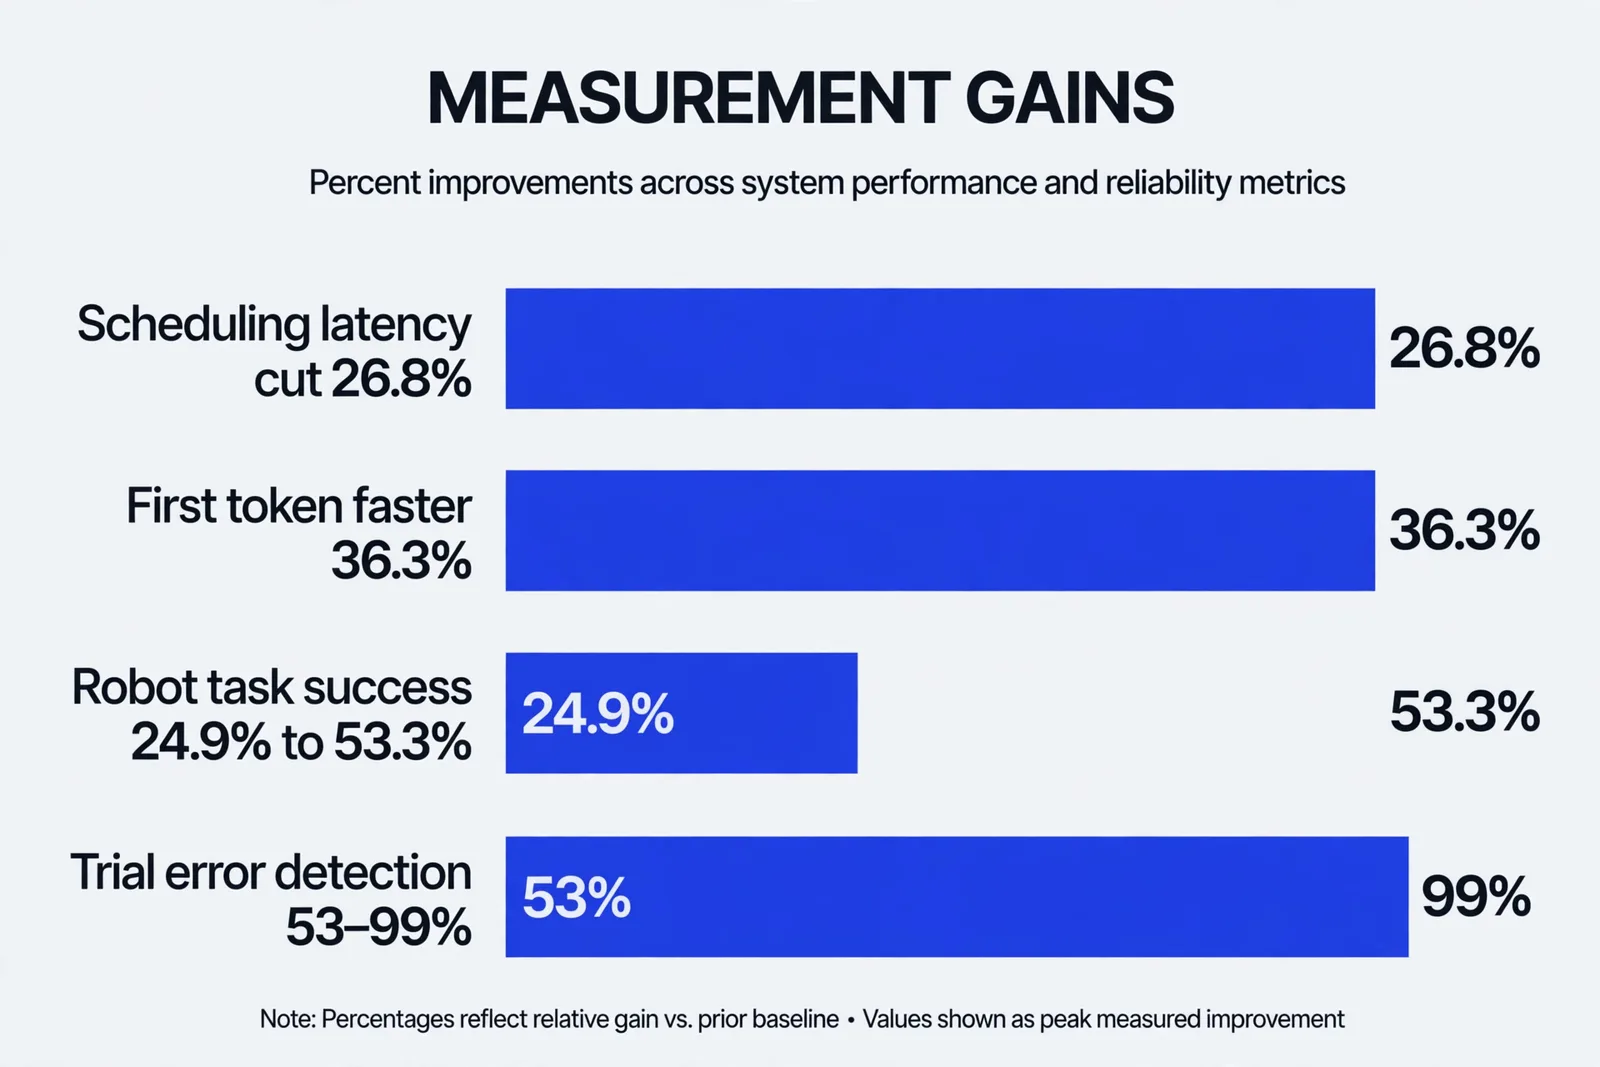
1. A scheduling preprint cut latency up to 26.8% and time to first token up to 36.3% — by placing work better, not by buying bigger cards. Baseten's optimized stack transcribes 7x more audio per second than vanilla vLLM at high concurrency.
2. In clinical AI, models caught major errors in trial reports at 53-99%, against 27% for untrained human reviewers — but flagged 2-29% of error types in clean control reports. The benchmark, not the model, decides whether you can trust the output.
3. Agent tooling shifted from judging models to judging work: Qodo flags code that passes tests yet misses the spec, and Patronus found RL alone nearly matched supervised fine-tuning plus RL on GitHub and Unreal tasks.
4. Robot learning got cheaper to judge too — CausGround lifted VirtualHome success from 24.9% to 53.3% without retraining, by reusing causal knowledge instead of paying for rollouts.
The pattern: measure first, ship second. Every team that skipped the measurement step paid for it in rework.
What measurement do you wish you had in place before your last agent rollout?
#AI #MachineLearning #SoftwareEngineering
This roundup was written by an agent from the stories below, each built from cited Synorb Manifests. Read the methodology and limitations, or send a correction.