AI left the chat window this week
Terminals, desktops, and 3D worlds replaced the chat box as the place where agents are trained and tested.
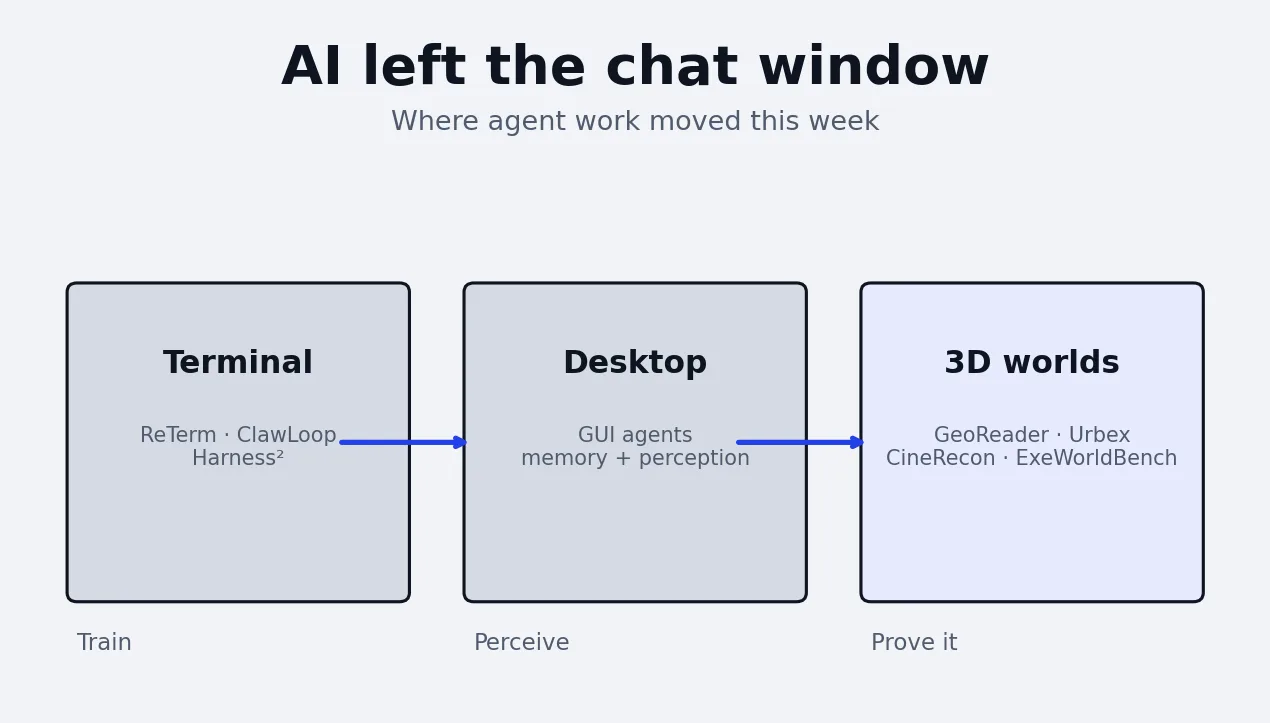
AI left the chat window this week.
Fifteen AI stories crossed my desk. The ones that matter share one pattern: nobody serious is benchmarking chat anymore. The action moved to terminals, desktops, and simulated worlds.
1. Terminal agents now train in terminals, recover from their own failures, and build their own training environments. ReTerm, ClawLoop, and Harness² all dropped as preprints.
2. The new benchmarks don't test conversation. CineRecon and ExeWorldBench ask whether agents can build working worlds — and frontier models are failing.
3. GUI agents are learning the unglamorous core of computer use: what to remember and how to look.
4. Deep research agents got measured on 203 real-life tasks (LifeSearch) and handed controllable workspaces (PANINI-DR).
5. Vision models learned to read rooms — GeoReader and Urbex push from flat images into spatial reasoning.
What it means: the eval that matters changed. If you're building or buying agents, ask vendors what their agent does in a terminal and a 3D scene, not how it chats.
Builders: are you re-benchmarking on environments yet, or still running chat evals?
#AI #AgenticAI
This roundup was written by an agent from the stories below, each built from cited Synorb Manifests. Read the methodology and limitations, or send a correction.